
Installation
PySpark is included in the official releases of Spark available in the Apache Spark website. For Python users, PySpark also provides pip installation from PyPI. This is usually for local usage or as a client to connect to a cluster instead of setting up a cluster itself.
This page includes instructions for installing PySpark by using pip, Conda, downloading manually, and building from the source.
Python Versions Supported
Python 3.8 and above.
Using PyPI
PySpark installation using PyPI is as follows:
pip install pyspark
If you want to install extra dependencies for a specific component, you can install it as below:
# Spark SQL pip install pyspark[sql] # pandas API on Spark pip install pyspark[pandas_on_spark] plotly # to plot your data, you can install plotly together. # Spark Connect pip install pyspark[connect]
For PySpark with/without a specific Hadoop version, you can install it by using PYSPARK_HADOOP_VERSION environment variables as below:
PYSPARK_HADOOP_VERSION=3 pip install pyspark
The default distribution uses Hadoop 3.3 and Hive 2.3. If users specify different versions of Hadoop, the pip installation automatically downloads a different version and uses it in PySpark. Downloading it can take a while depending on the network and the mirror chosen. PYSPARK_RELEASE_MIRROR can be set to manually choose the mirror for faster downloading.
PYSPARK_RELEASE_MIRROR=http://mirror.apache-kr.org PYSPARK_HADOOP_VERSION=3 pip install
It is recommended to use -v option in pip to track the installation and download status.
PYSPARK_HADOOP_VERSION=3 pip install pyspark -v
Supported values in PYSPARK_HADOOP_VERSION are:
- without : Spark pre-built with user-provided Apache Hadoop
- 3 : Spark pre-built for Apache Hadoop 3.3 and later (default)
Note that this installation of PySpark with/without a specific Hadoop version is experimental. It can change or be removed between minor releases.
Using Conda
Conda is an open-source package management and environment management system (developed by Anaconda), which is best installed through Miniconda or Miniforge. The tool is both cross-platform and language agnostic, and in practice, conda can replace both pip and virtualenv.
Conda uses so-called channels to distribute packages, and together with the default channels by Anaconda itself, the most important channel is conda-forge, which is the community-driven packaging effort that is the most extensive & the most current (and also serves as the upstream for the Anaconda channels in most cases).
To create a new conda environment from your terminal and activate it, proceed as shown below:
conda create -n pyspark_env conda activate pyspark_env
After activating the environment, use the following command to install pyspark, a python version of your choice, as well as other packages you want to use in the same session as pyspark (you can install in several steps too).
conda install -c conda-forge pyspark # can also add "python=3.8 some_package [etc.]" here
Note that PySpark for conda is maintained separately by the community; while new versions generally get packaged quickly, the availability through conda(-forge) is not directly in sync with the PySpark release cycle.
While using pip in a conda environment is technically feasible (with the same command as above), this approach is discouraged, because pip does not interoperate with conda.
For a short summary about useful conda commands, see their cheat sheet.
Manually Downloading
PySpark is included in the distributions available at the Apache Spark website. You can download a distribution you want from the site. After that, uncompress the tar file into the directory where you want to install Spark, for example, as below:
tar xzvf spark-3.5.0-bin-hadoop3.tgz
Ensure the SPARK_HOME environment variable points to the directory where the tar file has been extracted. Update PYTHONPATH environment variable such that it can find the PySpark and Py4J under SPARK_HOME/python/lib . One example of doing this is shown below:
cd spark-3.5.0-bin-hadoop3 export SPARK_HOME=`pwd` export PYTHONPATH=$(ZIPS=("$SPARK_HOME"/python/lib/.zip); IFS=:; echo "$]>"):$PYTHONPATH
Installing from Source
To install PySpark from source, refer to Building Spark.
How to Install PySpark on Windows
In this article, I will explain how to install and run PySpark on windows and also explain how to start a history server and monitor your jobs using Web UI.
- PySpark Install on Mac OS
- Apache Spark Installation on Windows
PySpark is a Spark library written in Python to run Python applications using Apache Spark capabilities. so there is no PySpark library to download. All you need is Spark.
Follow the below steps to Install PySpark on Windows.
Install Python or Anaconda distribution
Download and install either Python from Python.org or Anaconda distribution which includes Python, Spyder IDE, and Jupyter notebook. I would recommend using Anaconda as it’s popular and used by the Machine Learning & Data science community.
Install Java 8
To run the PySpark application, you would need Java 8 or a later version hence download the Java version from Oracle and install it on your system.
Post-installation set JAVA_HOME and PATH variable.
JAVA_HOME = C:\Program Files\Java\jdk1.8.0_201 PATH = %PATH%;C:\Program Files\Java\jdk1.8.0_201\bin
PySpark Install on Windows
PySpark is a Spark library written in Python to run Python applications using Apache Spark capabilities. so there is no PySpark library to download. All you need is Spark; follow the below steps to install PySpark on windows.
1. On Spark Download page, select the link “Download Spark (point 3)” to download. If you wanted to use a different version of Spark & Hadoop, select the one you wanted from drop-downs, and the link on point 3 changes to the selected version and provides you with an updated link to download.
2. After download, untar the binary using 7zip and copy the underlying folder spark-3.0.0-bin-hadoop2.7 to c:\apps
3. Now set the following environment variables.
SPARK_HOME = C:\apps\spark-3.0.0-bin-hadoop2.7 HADOOP_HOME = C:\apps\spark-3.0.0-bin-hadoop2.7 PATH=%PATH%;C:\apps\spark-3.0.0-bin-hadoop2.7\bin
Install winutils.exe on Windows
Download winutils.exe file from winutils, and copy it to %SPARK_HOME%\bin folder. Winutils are different for each Hadoop version hence download the right version from https://github.com/steveloughran/winutils
PySpark shell

Now open the command prompt and type pyspark command to run the PySpark shell. You should see something like this below.
Spark-shell also creates a Spark context web UI and by default, it can access from http://localhost:4041.
Web UI
Apache Spark provides a suite of Web UIs (Jobs, Stages, Tasks, Storage, Environment, Executors, and SQL) to monitor the status of your Spark application.

History Server
History servers, keep a log of all PySpark applications you submit by spark-submit, pyspark shell. before you start, first you need to set the below config on spark-defaults.conf
spark.eventLog.enabled true spark.history.fs.logDirectory file:///c:/logs/path
Now, start the history server on Linux or Mac by running.
$SPARK_HOME/sbin/start-history-server.sh
If you are running PySpark on windows, you can start the history server by starting the below command.
$SPARK_HOME/bin/spark-class.cmd org.apache.spark.deploy.history.HistoryServer

By default, History server listens at 18080 port and you can access it from the browser using http://localhost:18080/
By clicking on each App ID, you will get the details of the application in PySpark web UI.
Conclusion
In summary, you have learned how to install PySpark on windows and run sample statements in spark-shell
If you have any issues, setting up, please message me in the comments section, I will try to respond with the solution.
Related Articles
- Apache Spark Setup with Scala and IntelliJ
- Apache Spark Installation on Windows
- Spark Installation on Linux Ubuntu
- Spark Hello World Example in IntelliJ IDEA
- Spark Word Count Explained with Example
- Spark Setup on Hadoop Cluster with Yarn
- Spark Start History Server
- How to Check Spark Version
- Install PySpark on Ubuntu running on Linux
- Install PySpark in Anaconda & Jupyter Notebook
- Install PySpark in Jupyter on Mac using Homebrew
- How to Install PySpark on Mac
- Install Pyspark using pip or condo
- Dynamic way of doing ETL through Pyspark
How to Find PySpark Version?
PySpark Shell Command Usage with Examples
Install Anaconda & Run pandas on Jupyter Notebook - Pyspark: Exception: Java gateway process exited before sending the driver its port number
Naveen (NNK)
Naveen (NNK) is a Data Engineer with 20+ years of experience in transforming data into actionable insights. Over the years, He has honed his expertise in designing, implementing, and maintaining data pipelines with frameworks like Apache Spark, PySpark, Pandas, R, Hive and Machine Learning. Naveen journey in the field of data engineering has been a continuous learning, innovation, and a strong commitment to data integrity. In this blog, he shares his experiences with the data as he come across. Follow Naveen @ @ LinkedIn
Leave a Reply Cancel reply
This Post Has 3 Comments
Basha September 14, 2021 Reply
‘pyspark’ is not recognized as an internal or external command, operable program or batch file– please provide the solution for this error. It will be useful for others as well
NNK September 14, 2021 Reply
Hi Bash, Are you using windows or Linux platform? regardless you need to set the following on environment variables. Let me know if you don’t know how to set these.
SPARK_HOME = C:\apps\spark-3.0.0-bin-hadoop2.7
HADOOP_HOME = C:\apps\spark-3.0.0-bin-hadoop2.7
PATH=%PATH%;C:\apps\spark-3.0.0-bin-hadoop2.7\bin
Change the path according to your setup.

PySpark Tutorial
- PySpark Tutorial For Beginners
- PySpark – Features
- PySpark – Advantages
- PySpark – Modules & Packages
- PySpark – Cluster Managers
- PySpark – Install on Windows
- PySpark – Install on Mac
- PySpark – Web/Application UI
- PySpark – SparkSession
- PySpark – SparkContext
- PySpark – RDD
- PySpark – Parallelize
- PySpark – repartition() vs coalesce()
- PySpark – Broadcast Variables
- PySpark – Accumulator
PySpark DataFrame
- PySpark – Create an empty DataFrame
- PySpark – Convert RDD to DataFrame
- PySpark – Convert DataFrame to Pandas
- PySpark – show()
- PySpark – StructType & StructField
- PySpark – Column Class
- PySpark – select()
- PySpark – collect()
- PySpark – withColumn()
- PySpark – withColumnRenamed()
- PySpark – where() & filter()
- PySpark – drop() & dropDuplicates()
- PySpark – orderBy() and sort()
- PySpark – groupBy()
- PySpark – join()
- PySpark – union() & unionAll()
- PySpark – unionByName()
- PySpark – UDF (User Defined Function)
- PySpark – transform()
- PySpark – apply()
- PySpark – map()
- PySpark – flatMap()
- PySpark – foreach()
- PySpark – sample() vs sampleBy()
- PySpark – fillna() & fill()
- PySpark – pivot() (Row to Column)
- PySpark – partitionBy()
- PySpark – MapType (Map/Dict)
PySpark SQL Functions
- PySpark – Aggregate Functions
- PySpark – Window Functions
- PySpark – Date and Timestamp Functions
- PySpark – JSON Functions
PySpark Datasources
- PySpark – Read & Write CSV File
- PySpark – Read & Write Parquet File
- PySpark – Read & Write JSON file
- PySpark – Read Hive Table
- PySpark – Save to Hive Table
- PySpark – Read JDBC in Parallel
- PySpark – Query Database Table
- PySpark – Read and Write SQL Server
- PySpark – Read and Write MySQL
- PySpark – Read JDBC Table
PySpark Built-in Functions
- PySpark – when()
- PySpark – expr()
- PySpark – lit()
- PySpark – split()
- PySpark – concat_ws()
- Pyspark – substring()
- PySpark – translate()
- PySpark – regexp_replace()
- PySpark – overlay()
- PySpark – to_timestamp()
- PySpark – to_date()
- PySpark – date_format()
- PySpark – datediff()
- PySpark – months_between()
- PySpark – explode()
- PySpark – array_contains()
- PySpark – array()
- PySpark – collect_list()
- PySpark – collect_set()
- PySpark – create_map()
- PySpark – map_keys()
- PySpark – map_values()
- PySpark – struct()
- PySpark – countDistinct()
- PySpark – sum(), avg()
- PySpark – row_number()
- PySpark – rank()
- PySpark – dense_rank()
- PySpark – percent_rank()
- PySpark – typedLit()
- PySpark – from_json()
- PySpark – to_json()
- PySpark – json_tuple()
- PySpark – get_json_object()
- PySpark – schema_of_json()
Установка Spark NLP в Windows, Linux и Google Colab
В прошлой статье мы говорили о преимуществах Spark NLP. Сегодня рассмотрим, как установить Spark NLP и PySpark в Windows, Linux (Ubuntu) и Google Colab. В этой статье мы шаг за шагом разберем ход установки не только самой библиотеки, но и самого фреймворка Apache Spark на разных операционных системах.
Установка Spark NLP на Windows
Установка Apache Spark и Spark NLP в Windows потребует немного времени и сил, что не скажешь о Unix-системах. Нужно будет скачать соответствующие программы и установить переменные окружения.
Установка Apache Spark и Java
Если у вас не стоит Java 8, то скачиваете и устанавливаете OpenJDK 64-bit отсюда. При установке убедитесь, что переменная среды JAVA_HOME задана. В любом случае нужно будет проверить все переменные среды, если их не будет, то зададим вручную.
Скачайте winutils отсюда и положите файл в директорию C:\hadoop\bin . Если такой директории нет, то создайте.
Скачайте Apache Spark 2.4.7 отсюда и извлеките в директорию C так, что получится C:\spark-2.4.7-bin-hadoop2.7 .
Также может понадобится пакет vcredist_x64.exe со страницы Microsoft. Его нужно просто установить.
Определение переменных окружения
Переменные среды (environment variable) нужны для того, чтобы вы в командной строке могли запускать программы. Если вы можете запустить, например, Python в командной строке, значит в переменной среды PATH задан путь до выполняемой программы Python.
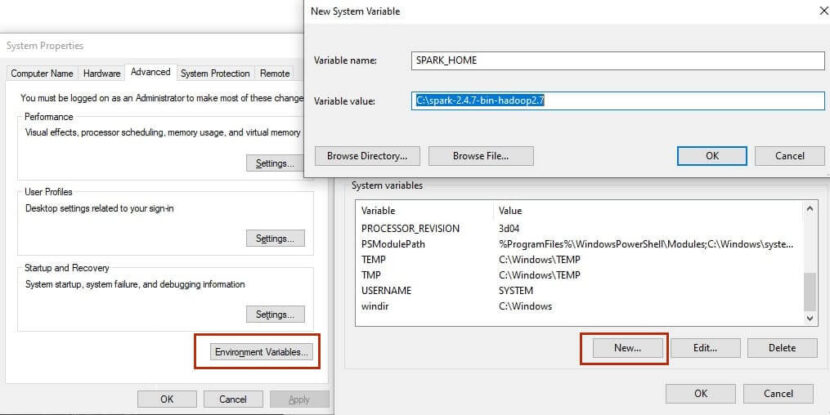
Чтобы установить переменные окружения можете использовать Поиск и ввести “переменные среды” (если система на английском, то “environment variables”). Там вам нужно будет добавить системные переменные среды.
Нужно установить две системные переменные HADOOP_HOME и SPARK_HOME , которые равны соответственно C:\hadoop и C:\spark-2.4.7-bin-hadoop2.7 (см. рисунок ниже).
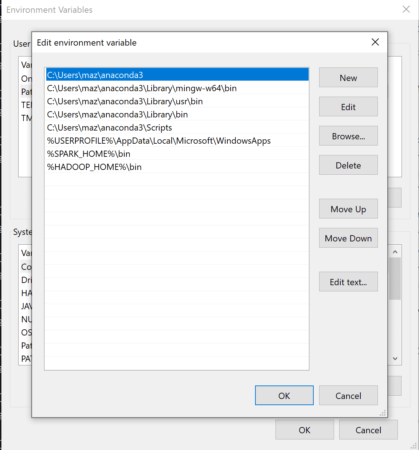
После этого нужно добавить пути до самих программ. Для этого в списке системных переменных найдите PATH, нажмите редактировать и добавьте %HADOOP_HOME%\bin и %SPARK_HOME%\bin , как это показано на рисунке ниже.
Также убедитесь, что у вас есть переменная JAVA_HOME и в пути стоит %JAVA_HOME%\bin . Если нет, то сделайте это вручную. По умолчанию после установки директория Java обычно находится в Program Files, поэтому переменная будет C:\Program Files\java .
Также нужно создать директории C:\temp и C:\temp\hive . Затем в командной строке вводите следующее (это разрешение на использование директории для всех пользователей):
%HADOOP_HOME%\bin\winutils.exe chmod 777 /tmp/ %HADOOP_HOME%\bin\winutils.exe chmod 777 /tmp/hive
Проверка работы установленных программ
Чтобы убедиться что все работает в командной строке можете ввести следующие команды:
java -version pyspark --version
Каждая из них выдаст свою версию. Нечто подобное для Java:
openjdk version "16" 2021-03-16 OpenJDK Runtime Environment (build 16+36-2231) OpenJDK 64-Bit Server VM (build 16+36-2231, mixed mode, sharing)
version 2.4.7 Using Scala version 2.11.12, OpenJDK Client VM, 1.8.0_41
Осталось только установить Spark NLP.
Установка Spark NLP
В той же командной строке установите Spark NLP, findspark и numpy (если его нет). Тут уже в зависимости каким пакетным менеджером вы пользуетесь: conda или pip. Через Pip установка Spark NLP выглядит слеующим образом:
pip install spark-nlp==2.7.5 findspark numpy
для Anaconda или Miniconda две команды:
conda install -c johnsnowlabs spark-nlp conda install -c conda-forge findspark numpy
Пакет findspark найдет Spark на компьютере, иначе бы мы не смоги импортировать pyspark.
На этом все. Можете запустить Python и проверить работоспособность установленных библиотек:
import findspark findsaprk.init() import sparknlp spark = sparknlp.start()
Установка Spark NLP на Ubuntu Linux
OpenJDK 8 есть в стандартных пакетах многих дистрибутивов, включая Ubuntu, Debian и Arch. А вот Spark придется качать вручную (можно через wget или curl). Иными словами, установить все необходимое можно, не выходя из эмулятора терминала.
Следующие команды установят OpenJDK, скачают архив Spark, разорхивирует его в созданной папке spark :
apt-get install -y openjdk-8-jdk-headless mkdir spark cd spark wget https://www.apache.org/dyn/closer.lua/spark/spark-2.4.7/spark-2.4.7-bin-hadoop2.7.tgz tar -xzvf spark-2.4.7-bin-hadoop2.7.tgz
Через команндую строку можем добавить переменные среды. Запишем их в файл .profile (можно также использовать .bashrc ):
echo "export JAVA_HOME=/usr/lib/jvm/java-8-openjdk-amd64" >> ~/.profile echo "export PATH=$PATH:$JAVA_HOME/bin" >> ~/.profile echo "export SPARK_HOME=~/spark" >> ~/.profile echo "export PATH=$PATH:$SPARK_HOME/bin:$SPARK_HOME/sbin" >> ~/.profile echo "export PYSPARK_PYTHON=python3" >> ~/.profile echo "export PYSPARK_DRIVER_PYTHON=jupyter" >> ~/.profile echo "export PYSPARK_DRIVER_PYTHON_OPTS=notebook" >> ~/.profile
Установка пакетов Spark NLP осуществляется также, как это указано выше.
Ленивый способ – Google Colab
Если вы не хотите ничего устанавливать у себя на компьютере, то вы можете воспользоваться Google Colab. Там тоже стоит Ubuntu, но все делается гораздо проще.
В свою первую ячейку Google Colab скопируйте следующие строки:
!apt-get install -y openjdk-8-jdk-headless -qq > /dev/null !pip install -q pyspark==2.4.7 !pip install -q spark-nlp==2.7.5 import os os.environ["JAVA_HOME"] = "/usr/lib/jvm/java-8-openjdk-amd64" os.environ["PATH"] = os.environ["JAVA_HOME"] + "/bin:" + os.environ["PATH"]
И все. Можете работать с PySpark и Spark NLP, тренировать модели, эксплуатировать GPU. О том, что такое Google Colab и как в нем работать смотрите видеоролик ниже.
Еще больше подробностей о работе в Apache Spark с обучением на реальных примерах Data Science вы узнаете на специализированном курсе «Основы Apache Spark для разработчиков» в лицензированном учебном центре обучения и повышения квалификации разработчиков, менеджеров, архитекторов, инженеров, администраторов, Data Scientist’ов и аналитиков Big Data в Москве.