
Jupyterhub что это
A multi-user version of the notebook designed for companies, classrooms and research labs
What is JupyterHub?
JupyterHub brings the power of notebooks to groups of users. It gives users access to computational environments and resources without burdening the users with installation and maintenance tasks. Users — including students, researchers, and data scientists — can get their work done in their own workspaces on shared resources which can be managed efficiently by system administrators.
JupyterHub runs in the cloud or on your own hardware, and makes it possible to serve a pre-configured data science environment to any user in the world. It is customizable and scalable, and is suitable for small and large teams, academic courses, and large-scale infrastructure.
Key features of JupyterHub
Customizable — JupyterHub can be used to serve a variety of environments. It supports dozens of kernels with the Jupyter server, and can be used to serve a variety of user interfaces including the Jupyter Notebook, Jupyter Lab, RStudio, nteract, and more.
Flexible — JupyterHub can be configured with authentication in order to provide access to a subset of users. Authentication is pluggable, supporting a number of authentication protocols (such as OAuth and GitHub).
Scalable — JupyterHub is container-friendly, and can be deployed with modern-day container technology. It also runs on Kubernetes, and can run with up to tens of thousands of users.
Portable — JupyterHub is entirely open-source and designed to be run on a variety of infrastructure. This includes commercial cloud providers, virtual machines, or even your own laptop hardware.
The foundational JupyterHub code and technology can be found in the JupyterHub repository. This repository and the JupyterHub documentation contain more information about the internals of JupyterHub, its customization, and its configuration.
Deploy a JupyterHub
The Jupyter Community curates two JupyterHub “distributions” for deploying in the cloud. Follow the links below for more information.
Zero to JupyterHub for Kubernetes deploys JupyterHub on Kubernetes using Docker, allowing it to be scaled and maintained efficiently for large numbers of users. Zero to JupyterHub is a Helm Chart for deploying JupyterHub quickly, as well as a guide to deploying and configuring your JupyterHub on Kubernetes.
The Littlest JupyterHub, a recent and evolving distribution designed for smaller deployments, is a lightweight method to install JupyterHub on a single virtual machine. The Littlest JupyterHub (also known as TLJH), provides a guide with information on creating a VM on several cloud providers, as well as installing and customizing JupyterHub so that users may access it at a public URL.
Join the community
Like all Project Jupyter efforts, JupyterHub is an open-source and community-driven project. We’d love for you to join our community and contribute code, time, comments, or appreciation.
The JupyterHub Gitter Channel is a place where the JupyterHub community discuses developments in the JupyterHub technology, as well as best-practices in deploying and debugging.
Jupyter Notebook
Jupyter Notebook (Юпитер-ноутбук) — это программа-блокнот для записи, передачи и запуска кода. Ей можно пользоваться как своеобразной средой разработки. Она существует как веб-сервис, то есть доступна через интернет и позволяет передавать код другим разработчикам.
«IT-специалист с нуля» наш лучший курс для старта в IT
Чаще всего среду используют для Python, но она существует и для других языков программирования. Jupyter Notebook поддерживает языки Ruby, Perl, R, MATLAB, Julia и другие. Часто это специализированные языки для задач, которые подразумевают быстрое написание и выполнение маленькой программы.
Отличие Юпитер-ноутбука от традиционных сред разработки — в его интерактивности. Программа позволяет запускать отдельные участки и блоки кода, выполнять их в любом порядке. А результаты работы сразу можно вывести в то же окно рядом с кодом.
Юпитер-ноутбуками во множественном числе называют документы с кодом, созданные в среде.
Профессия / 8 месяцев
IT-специалист с нуля
Попробуйте 9 профессий за 2 месяца и выберите подходящую вам
Кто пользуется Jupyter Notebook
Чаще всего с юпитер-ноутбуками работают программисты на Python. Так сложилось исторически: проект вырос из IPython, особого расширения для «Питона», хотя сейчас у платформы есть поддержка и для других языков.
Основные сферы использования среды — big data и data science, машинное обучение, математическая статистика и аналитика. В этих направлениях пригодилась способность Jupyter Notebook выводить данные туда же, где написан код. Получается как бы страница блокнота: в одном месте собраны участки кода, результаты их выполнения, таблицы, участки и графики.
Но попробовать Jupyter Notebook для своих проектов можно и вне этой сферы. Если ваша отрасль подразумевает частую работу с документами и графиками, возможно, вам понравится эта среда.
Для чего нужен Jupyter Notebook
- Писать код в специальной среде с подсветкой синтаксиса, исправлением ошибок и другими возможностями IDE.
- Запускать разные участки кода в произвольной последовательности или написанную программу целиком.
- Загружать какие-то данные, обрабатывать и преобразовывать их, не затрагивая при этом другие участки программы.
- Вставлять и выводить результаты, включая визуализацию, прямо посреди кода.
- Делиться кодом с другими разработчиками и давать им общий доступ к проекту.
- Организовывать командную работу, когда у каждого программиста — своя задача, связанная с другими.
- Писать сопровождающий текст и оформлять «документ» так, чтобы он выглядел красиво и понятно.
Юпитер-ноутбук дает те же возможности, что стандартная IDE, но при этом он более гибкий и, как говорят его создатели, документоцентричный. То есть все написанное выглядит как документ и собрано в одном месте.
Две версии программы
Jupyter Notebook существует в двух версиях: облачная и для компьютера. Обе бесплатные, с открытым исходным кодом. Облачной версией можно пользоваться прямо через браузер. Нужно только подключение к интернету: принцип работы у нее как, например, у Google Документов.
Локальная версия дает возможность работать с редкими библиотеками, которых может не быть в облаке. К тому же на отдельном компьютере среда способна работать быстрее, а у разработчика больше контроля.
Для загрузки локальной версии понадобится Python и установленный в него пакет Jupyter. Его можно скачать через консоль с помощью встроенной в Python утилиты pip. А еще Юпитер-ноутбук входит в состав расширения Anaconda.
Скачанные пакеты запустят локальный Jupyter-сервер, и интерфейс среды откроется в браузере. Им можно пользоваться на свое усмотрение, но доступа к облаку у локального сервера нет.
Как выглядит работа с Jupyter Notebook
Интерфейс программы похож одновременно на текстовый редактор и среду разработки. Можно представить Юпитер-ноутбук как документ с возможностью писать и выполнять код. Там есть инструменты и для форматирования самого документа, и для запуска или отладки программ.
Программирование. Если разработчик пишет на Python, он может просто создать файл и начать программировать, как в обычной среде. Для подключения других языков понадобится воспользоваться специальными командами — их называют магическими. Магическая команда выглядит как %% и переключает среду на указанный язык. Так можно подключить даже bash, консольный язык команд для операционных систем.
Код в Юпитер-ноутбуке разделен на отдельные участки — блоки. Каждый блок можно запускать отдельно от других. Между блоками может находиться текст, графика, результаты выполнения кода и так далее. Получается своеобразный интерактивный документ — одновременно программа и текстовый файл.
Тексты. Кроме написания кода, в Юпитер-ноутбуке можно писать текст. Это не просто комментарии: в среде есть возможности для создания полноценной интерактивной статьи с кодом. Jupyter Notebook поддерживает разметку Markdown, которая позволяет создавать заголовки и списки, добавлять интерактивные ссылки и делать многое другое.
Так можно создавать аналитические отчеты, статьи и интерактивные параграфы для учебников. Поэтому Jupyter Notebook любят в аналитике данных и статистике, где часто бывают нужны точные отчеты и визуализации с результатами.
Курс для новичков «IT-специалист
с нуля» – разберемся, какая профессия вам подходит, и поможем вам ее освоить
Графика. Картинки, графики и визуализацию можно добавлять как в текстовый документ. Кроме того, Юпитер-ноутбук поддерживает математические формулы. Графику можно выводить интерактивно: запускать блоки кода, чтобы они отрисовали нужную визуализацию. Результат последнего запуска не сотрется после выхода: он останется в документе, его смогут просмотреть другие люди или сам владелец, когда в следующий раз откроет ноутбук.
Для визуализации Jupyter Notebook использует библиотеки языков. Например, графики для Python чаще всего рисуются через Matplotlib. Юпитер-ноутбук поддерживает и другие расширения для визуализации, в том числе в интерактивном режиме. Правда, некоторые из них платные или медленные.
Запуск. В Jupyter Notebook, как и в любой IDE, можно запустить код. Отличие в том, что результаты показываются сразу и отображаются в том же документе. Для запуска есть специальная панель с кнопками: запустить, остановить, отладить и так далее.
Если код работает не так, можно переписать его и запустить снова. Выведенный в документ результат при этом изменится. Когда все будет готово, можно сохранять файл и выходить: при следующем входе все результаты будут на месте и код не понадобится запускать заново.
Сохранение и общий доступ. В случае с локальной версией файлы сохраняются на устройстве. К облачной понадобится подключить хранилище, в котором будут лежать созданные ноутбуки. Чаще всего пользуются Google Colab — ответвлением Google Drive для разработки и исследований. Возможности Colab позволяют запускать код в браузере, сохранять документы и делиться ими.
Для документа в облаке можно настроить общий доступ, чтобы его могли увидеть другие специалисты. Это удобно, например, при создании отчетов или при командной разработке.
Другие проекты
Есть еще одна версия среды-блокнота от тех же разработчиков, она называется Jupyter Lab. У нее несколько иной интерфейс и похожий принцип работы. Ее позиционируют как улучшенную версию Юпитер-ноутбука, которая позволяет «собирать» вместе несколько рабочих задач.
Для того чтобы делиться кодом с командой, есть JupyterHub — проект, который позволяет запустить собственный юпитер-сервер и дать к нему доступ другим людям.
Google Colab тоже можно использовать как интерактивный блокнот, это не только хранилище. Но у Jupyter Notebook шире возможности для разработчиков.
Преимущества Jupyter Notebook
Наглядность. Все находится в одном месте: код, сопровождающий текст, результаты и визуализация. Поэтому нужная информация всегда под рукой, а оформить ее можно в понятном формате. При этом Юпитер — полноценная среда, в которой можно запускать код и проверять его.
Документоориентированность. Это преимущество связано с наглядностью. Юпитер-ноутбук выглядит как документ: глава из книги, отчет или что-то еще. Благодаря такому отображению с его помощью можно создавать отличные интерактивные документы по работе или для обучения. Например, отчет, который при запуске кода сам рисует график, или учебник, демонстрирующий работу программы прямо на страницах.
Широкие возможности. Jupyter Notebook мощный и гибкий. В нем все шире поддержка разных языков, в том числе специфических, есть нужные разработчику библиотеки. Облачная версия предоставляет мощности для отрисовки графиков — их тоже можно визуализировать с помощью разных инструментов. Markdown позволяет делать документы красивее и форматировать их. Есть и другие расширения: для создания презентаций, экспортирования документов в HTML и прочих функций.
Моментальный вывод результата. Результат выполненной программы в стандартной IDE открывается в отдельном окне или записывается в файл. В любом случае его довольно редко бывает можно просмотреть внутри среды, если это не текст и не число, а, скажем, график или таблица. А в Jupyter Notebook все отображается сразу под кодом, в том же документе. Удобно и, главное, видно сразу.
Командная работа. Возможности для командной работы позволяют делиться документом с другими, запускать собственный сервер для группы разработчиков, совместно редактировать и исправлять ошибки. Все это в одной и той же версии документа, а не в разных его экземплярах (как было бы, например, с передачей друг другу файлов с кодом).
Недостатки Jupyter Notebook
Неуниверсальность. Если вам нужно только писать код, а тексты и графики ни к чему, Юпитер-ноутбук может оказаться попросту избыточным решением. К тому же он не подходит для крупных проектов, где все связано между собой. Он рассчитан на написание и выполнение отдельных маленьких «кусочков» программы, а не ее целиком. Держать там целый большой продукт будет неудобно как в отладке, так и в запуске.
Сложный перенос. Переносить код из Jupyter Notebook в другие среды — не самая простая задача все из-за той же структуры, основанной на маленьких блоках. Просто скопировать не получится. Нужно будет удалить лишнее и переписать часть кода.
Поэтому Jupyter Notebook не рекомендуют как основную среду, особенно для больших проектов. Но это удобный вспомогательный инструмент.
IT-специалист с нуля
Наш лучший курс для старта в IT. За 2 месяца вы пробуете себя в девяти разных профессиях: мобильной и веб-разработке, тестировании, аналитике и даже Data Science — выберите подходящую и сразу освойте ее.
Статьи по теме:
- Как научиться работе с данными самостоятельно на Python
- Что такое Google Colab и кому он нужен
A Practical Guide
Jupyter Notebook is an open source application, used by data scientists and machine learning professionals to author and present code, explanatory text, and visualizations. JupyterHub is an open source tool that lets you host a distributed Jupyter Notebook environment.
With JupyterHub, users can log in to the server, and write Python code in a web browser, without having to install software on their local machine. The Jupyter Notebook and JupyterLab interface provided by JupyterHub is the same as the Jupyter interface running locally. JupyterHub supports web browsers, tablets and smartphones.
JupyterHub should not be confused with cloud-based services for running Jupyter Notebooks—such as Google Colab, Microsoft Azure Notebooks, and Binder. Users or organizations looking for a managed, hosted Jupyter Notebook solution can leverage one of these services. JupyterHub is a do-it-yourself solution that lets you install and manage your own Jupyter Notebook server.
This is part of our series of articles about machine learning engineering.
In this article, you will learn:
- What is JupyterHub?
- Do You Need JupyterHub?
- What’s the Difference Between Jupyter Notebook, JupyterLab, and JupyterHub?
- What Problem Does JupyterHub Solve?
- What are the Use Cases of JupyterHub?
- JupyterHub Features and Capabilities
- JupyterHub Architecture
- The Subsystems: Hub, Proxy, Single-User Notebook Server
- How the Subsystems Interact
- JupyterHub Tutorial 1: Installing JupyterHub on Local Server
- Prerequisites
- Installation
- Start the Hub Server
- JupyterHub Tutorial 2: Deploying Using Kubernetes
- Prepare Configuration File
- Update Repo
- Install Helm Chart
- Wait for JupyterHub to Deploy and Access It
- Configuring User Environments in JupyterHub
- Distributing Additional Packages
- Configuring Jupyter and IPython for Users
- Named Servers
Do You Need JupyterHub?
What’s the Difference Between Jupyter Notebook, JupyterLab, and JupyterHub?
Jupyter Notebooks provides a document specification and a graphical user interface for editing documents. Here are several aspects to know about Jupyter Notebooks:
- A Jupyter Notebook is a .ipynb specification document file—composed of narrative text, code cells, and outputs.
- A Jupyter Notebook comes with a graphical user interface—which enables you to edit .ipynb documents.
Document editing is not exclusive to the Jupyter Notebook interface. You can also use alternatives like JupyterLab, Google Colab, nteract, and Kaggle.
JupyterLab provides a user interface designed for interactive computing. Here are several aspects to know about JupyterLab:
- JupyterLab is a user interface—designed to provide extensible and flexible interactive computing.
- JupyterLab provides extensions—some of which are designed for Jupyter Notebooks. There are also extensions designed for specific parts of the data science pipeline.
JupyterHub provides an application designed for the management of Jupyter Notebooks. Here are several aspects to know about JupyterHub:
- JupyterHub is an application—designed to help you manage multiple-users sessions of interactive computing.
- JupyterHub provides connectivity—that enables you to connect users with the infrastructure required for their sessions.
- JupyterHub enables remote access—to JupyterLab as well as Jupyter Notebooks. You can use this option to let multiple users gain remote access to Jupyter resources.
What Problem Does JupyterHub Solve?
JupyterHub enables collaboration by providing a shared platform for data scientists and relevant stakeholders. You can use JupyterHub to create a data science workflow and deploy it on your infrastructure. This level of flexibility enables you to use the tools of your choice, including Jupyter Notebooks and a python stack, and control access to resources and the environment.
What are the Use Cases of JupyterHub?
There is a wide range of applications for JupyterHub. It is used by large data centers providing computing resources to data scientists, major research labs, large universities serving data science students and researchers, companies with extensive data science operations, and online communities that promote collaborative data science and machine learning.
JupyterHub is usually used to enable collaboration between small and large teams:
- Small teams—use JupyterHub to enable sharing interactive computing resources and analytics. Small teams include research labs, data science teams, or any collaborative project.
- Large teams—use JupyterHub for providing multiple users with access to corporate resources like data, hardware, and analytics programs. Lard teams include any large group of remote users like departments and large classes.
JupyterHub Features and Capabilities
JupyterHub provides the following key capabilities:
- Sets up a Jupyter Notebook or JupyterLab environment for up to tens of thousands of users—supports Kubernetes for large-scale deployments.
- Supports many different languages, environments, and user interfaces, with a variety of Jupyter kernels developed by the community (see the list of available kerners). You can deliver one or more existing kernels to JupyterHub users, or develop your own.
- Provides pluggable authentication, enabling flexible authentication for some or all users, using several authentication protocols including OAuth and GitHub.
- Scales up by sharing the same server with multiple users, or running multiple isolated containers.
- Can be deployed on any infrastructure, including public cloud providers, virtual machines, or locally on an on-premise laptop or server.
JupyterHub Architecture
Let’s dive a bit deeper and see how JupyterHub works behind the scenes.
The Subsystems: Hub, Proxy, Single-User Notebook Server
The JupyterHub architecture is designed to supply each single user of a group with a Jupyter Notebook server. To achieve this, the architecture uses the following three main subsystems:

- Hub—designed to manage user accounts and authentication. The hub uses a Spawner when coordinating single-user notebook servers.
- Proxy—serves as the public-facing component. This proxy dynamically routes HTTP requests to single-user notebook servers and the Hub.
- Single-user notebook server—an object called Spawner starts a single-user notebook when a user logs in.
JupyterHub Tutorial 1: Installing JupyterHub on Local Server
Prerequisites
To install JupyterHub, you need a system with the following requirements:
- Linux / Unix with Python 3.5 or higher, Node.js and the npm package manager.
- Install a Pluggable Authentication Module (PAM) with a default authenticator (if not included in your OS distribution).
- Install Jupyter Notebook 4 or higher.
- Domain name
- SSL/TLS certificate to enable secure communication over HTTPS
How the Subsystems Interact
To access JupyterHub from a web browser, a user can either use the domain name or IP address of the server.
The Hub and the proxy
The Hub is responsible for handling logins and spawning single-user notebooks servers. When a user attempts to gain access, the Hub spawns a proxy based on the JupyterHub configuration. The proxy can then forward all requests to the Hub. Only the proxy is allowed to listen on a public interface.
Types of authenticators
There are several authenticators available for controlling access to JupyterHub. PAM is the default authenticator. It uses the user accounts that are located on the same server running JupyterHub. PAM requires creating a user account per each user. Other authenticators can enable users to log in using single-sign-on.
Spawners
A spawner creates a notebook server for each user, and defines how that notebook will be configured. By default, a spawner starts a server on the machine currently running the system username. Alternatively, you can start the notebook server within a separate container. You can use orchestrators like Docker when you opt to use containers.
Installation
Install JupyterHub and test your installation using one of the following commands:

Start the Hub Server
Run the following command to start the Hub Server: jupyterhub
Visit the address https://localhost:8000 in your local browser and log in with your UNIX credentials.
Note that if you want to allow multiple users to log in to the Hub Server, you need to start JupyterHub with root privileges, as follows: sudo jupyterhub
JupyterHub Tutorial 2: Deploying Using Kubernetes
For larger deployments, you can deploy JupyterHub via Kubernetes, the popular container orchestrator. The instructions and code below are abbreviated from the full Zero to JupyterHub Kubernetes tutorial.
Related content: read our guide to Kubernetes architecture for machine learning
Prepare Configuration File
Start by preparing a configuration file called config.yaml. This includes several values used to configure the JupyterHub Helm chart. You can use this chart to deploy a working version of JupyterHub to Kubernetes.
You can keep the Helm values as default, but there is one value that is mandatory to set—the secretToken value which is used as your security token. Generate a random 32 byte hex string and set it in the configuration as follows:
Update Repo
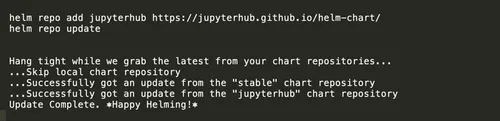
Add the JupyterHelm repository to helm, so you can install it without using long URLs. Run the following command (shown together with its output).
Install Helm Chart
Install the Helm charts specified in config.yaml. Run the helm upgrade command from the directory containing the configuration file.
Within the command, specify a RELEASE—a Helm release name, used to distinguish between chart installations and a NAMESPACE—this is the Kubernetes namespace, used to group Kubernetes resources associated with JupyterHub. The official tutorial recommends using the value jhub for both.

Wait for JupyterHub to Deploy and Access It
Wait for the hub and proxy pods to reach Running state. You can check their state by running the command kubectl get pod —namespace jhub
Once they are running, run the command kubectl get service —namespace jhub and see the external IP defined for the proxy-public load balancer:
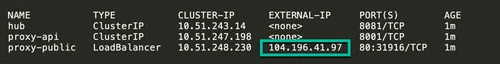
To use JupyterHub, enter the external IP into your browser. JupyterHub initially runs a default virtual authenticator, so you can use any username and password to access it.
That’s it! You just ran JupyterHub on Kubernetes using the Zero to JupyterHub Helm chart.
Configuring User Environments in JupyterHub
JupyterHub is used to provision a Jupyter Notebook environment to multiple users. In most cases, you will want to customize the Jupyter Notebook user experience. Here are a few ways to achieve this.
Distributing Additional Packages
In many cases, users will need to use additional packages together with Jupyter Notebook. To make these packages available, you’ll typically install it system-wide or in a shared environment.
Make sure that the installation location of any additional packages is the same as the location of jupyterhub-singleuser. This location should be readable and executable by the users. If you want to enable users to install their own packages, make the location writable as well.
Configuring Jupyter and IPython for Users
JupyterHub admins generally need to install and configure the same environment for all JupyterHub users.
Both Jupyter and IPython support “system wide” configuration, which lets you define configuration in one place for all users. It is a best practice to only use system-wide configuration, and avoid placing configuration files in user home directories.
In most cases, the system-wide configuration is located in the /etc/
For example, here is how to enable a specific Jupyter Notebook configuration setting for all users, by setting it in the system-wide /etc/jupyter/jupyter_notebook_config.py file:
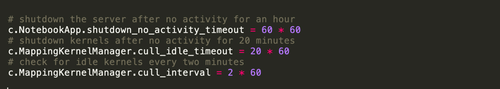
Note that system-wide configuration can be slightly different depending on how you deploy user environments—a shared system with multi-user hosts, or a container-based system with an isolated environment for each user.
Named Servers
By default, JupyterHub distribution has one server per user. However, if necessary, you can enable multiple servers per user. This is useful in deployments where users are allowed to start servers by requesting resources in a cloud orHPC environment.
You can let users run multiple Jupyter servers simultaneously, using the following command:
c. JupyterHub.allow_named_servers = true
Scaling Machine Learning Infrastructure with Run:AI
When running JupyterHub to serve a large group of data science users, you also need to maintain a machine learning infrastructure, enabling them to run experiments in an efficient and timely manner.
Run:AI automates resource management and orchestration for machine learning infrastructure. With Run:AI, you can automatically run as many compute intensive experiments as needed.
Here are some of the capabilities you gain when using Run:AI:
- Advanced visibility—create an efficient pipeline of resource sharing by pooling GPU compute resources.
- No more bottlenecks—you can set up guaranteed quotas of GPU resources, to avoid bottlenecks and optimize billing.
- A higher level of control—Run:AI enables you to dynamically change resource allocation, ensuring each job gets the resources it needs at any given time.
Run:AI simplifies machine learning infrastructure pipelines, helping data scientists accelerate their productivity and the quality of their models.
JupyterHub или как перестать бояться pip install
Всем привет, сегодня я расскажу о том, как мы переехали на наш велосипед в виде JupyterHub, и он оказался удобным. У нас в компании работают ~20 дата саентистов и в своей работе они используют множество Open Source-инструментов: Airflow, Hadoop, Hive, Spark и т.д. Но в данной статье речь пойдет исключительно о JupyterHub, точнее говоря о боли, которая преследовала администраторов, и как мы успешно ее побороли.
Почему мы выбрали JupyterHub
JupyterHub — это тот же Jupyter, только ставится он на отдельный сервер и работает как клиент-серверное веб-приложение.
Преимущества тут очевидны:
- Вам не нужно беспокоиться об установке Jupyter’а и его окружения;
- Не тратятся локальные ресурсы на вычисления;
- Серверные мощности обычно выше локальных.
Но есть и недостатки:
- Ресурсы сервера делятся на всех пользователей. По сути кто первый – того и тапки;
- Одна среда на всех: вы будете пользоваться только тем ПО, которое установлено на сервере.
- Обновление через боль. Установка нового ПО или обновление существующего требует согласования со всеми пользователями JupyterHub’а.
Просто представьте насколько задача усложнится, если на ваших серверах нет интернета. А политика безопасности настолько забюрократизирована, что процедура установки ПО будет съедать всё ваше время.
В игру вступает Kernel
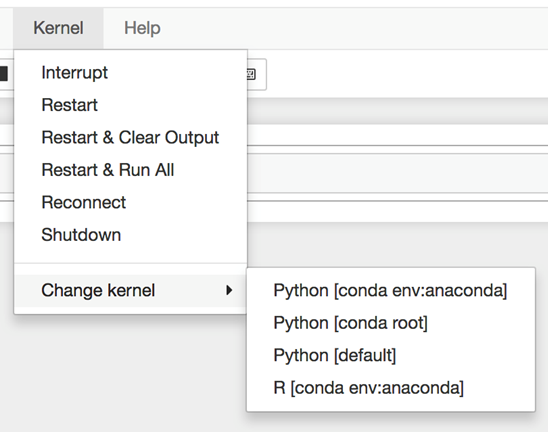
Частично вышеописанные проблемы решаются с помощью kernel’ов — виртуальных сред (venv). Вы устанавливаете в них необходимые пакеты, затем переносите их на JupyterHub, после чего данное ядро становится доступным для выбора в интерфейсе лэптопа. А весь код, написанный на лэптопе, будет работать именно в этом окружении.
Но на практике оказалось, что kernel’ы оказались еще бо́льшей бедой: их также необходимо поддерживать и регулярно обновлять, плюс со временем они обрастали зависимостями и legacy-кодом. А до бесконечности создавать новые kernel’ы невозможно.
Все это вызывало негатив со всех сторон: дата саентисты не могли получить своевременный доступ к нужному ПО. А администраторам приходилось постоянно что-то досогласовывать, устанавливать и переустанавливать. Так продолжать мы не могли, поэтому мы решили оптимизировать работу дата саентистов.
Что придумали
Чтобы избавить саентистов (и админов) от боли, мы поставили перед собой следующие цели:
- Установить/обновить любое ПО можно без привлечения администраторов;
- Установить/обновить ПО можно в любой момент;
- Установленное одним пользователем ПО не должно влиять на работу остальных пользователей;
- Установленное ПО не должно негативно влиять на сервер в целом.
После исследования мы решили использовать связку Jupyterhub + Docker, а kernel’ы собирать в GitLab CICD, чтобы затем доставлять их на сервера Jupyterhub.

Схема работы
Схема работы следующая: для каждого пользователя в GitLab создана отдельная папка и, когда пользователю необходимо создать новый kernel, он:

- Создает в своей папке новый проект (папку);
- Создает файл requirements.json и описывает в нем: 2.1 Название kernel’а 2.2 Имя docker-образа (скачивается из DockerHub’а, либо с нашего локального репозитория, где хранятся наши кастомные образы). 2.3 Python-библиотеки для установки и их версии
- В случае необходимости редактирует Dockerfile;
- Запускает CICD-процесс, в котором: 4.1 Собирается ядро; 4.2 Выполняются команды из Dockerfile. 4.3 Устанавливаются библиотеки из requirements.json. 4.4 Ядро копируется на сервер JupyterHub.
Новое ядро сразу становится доступными для работы в JupyterHub’е. А в случае необходимости дата саентист самостоятельно правит параметры своего ядра и пересобирает его.
Что это нам дало
Теперь большая часть работы выполняется дата саентистами без привлечения администраторов. После 10 тысяч сборок kernel’ов мы сэкономили массу времени на процедурах согласований и самой установке.
Эффективность обоих сторон увеличилась, а админы привлекаются крайне редко —только для решения сложных вопросов. Цели 1 и 2 выполнены.
Доступ в интернет для скачивания библиотек мы реализовали посредством прокси-сервера, с которого разрешено обращаться только к репозиторию pip. Все ПО работает исключительно внутри контейнера. Что бы там не произошло — это никак не повлияет на работу других пользователей. Так мы закрыли вопрос с целями 3 и 4.
А теперь пара технических моментов:
Пример конфига ядра
kernel.json
< "argv": [ "/usr/bin/docker", "run", "--network=host", "--rm", "-v", ":/connection-spec", "-v", "/home/anikishin/work:/root/work", "************/docker/registry/anikishin_dataflow:latest", "python", "-m", "ipykernel_launcher", "-f", "/connection-spec" ], "display_name": "anikishin_dataflow", "language": "python", "env": <> >Использование —network=host объясняется тем, что во время работы pyspark на машине открывается случайный порт и кластер Hadoop должен иметь доступ к клиенту.
Пример сборки ядра
$ LOGIN=`echo "$" | awk ''` $ echo -e "export PATH_TO_KERNEL=/$/$\nLOGIN=$\nKERNEL=$" >.env $ source ./.env $ PYTHON_VERSION=`/bin/python3 $/parser.py $/$/requirements.json python_version` $ sed "s/PYTHON_VERSION/$/g" $/$/Dockerfile FROM python:3.8-slim WORKDIR /root/work COPY requirements.txt /tmp/requirements.txt RUN pip install --upgrade -r /tmp/requirements.txt$ sed -i "s/PYTHON_VERSION/$/g" $/$/Dockerfile $ /bin/python3 $/parser.py $/$/requirements.json libs > $/$/requirements.txt $ echo "IMAGE_NAME=`/bin/python3 $/parser.py $/$/requirements.json image_name`" >> ./.env $ echo "IMAGE_VERSION=`/bin/python3 $/parser.py $/$/requirements.json image_version`" >> ./.env $ source ./.env $ docker build --no-cache -t ************:5005/docker/registry/$_$:$ $/$/ Step 1/4 : FROM python:3.8-slim 3.8-slim: Pulling from library/python 42c077c10790: Already exists f63e77b7563a: Pulling fs layer 5215613c2da8: Pulling fs layer 9ca2d4523a14: Pulling fs layer e97cee5830c4: Pulling fs layer e97cee5830c4: Waiting 9ca2d4523a14: Verifying Checksum 9ca2d4523a14: Download complete f63e77b7563a: Verifying Checksum f63e77b7563a: Download complete 5215613c2da8: Verifying Checksum 5215613c2da8: Download complete f63e77b7563a: Pull complete 5215613c2da8: Pull complete 9ca2d4523a14: Pull complete e97cee5830c4: Verifying Checksum e97cee5830c4: Download complete e97cee5830c4: Pull complete Digest: sha256:0e07cc072353e6b10de910d8acffa020a42467112ae6610aa90d6a3c56a74911 Status: Downloaded newer image for python:3.8-slim ---> 61c56c60bb49 Step 2/4 : WORKDIR /root/work ---> Running in 4baf6a21fb37 Removing intermediate container 4baf6a21fb37 ---> 0f5165f4c567 Step 3/4 : COPY requirements.txt /tmp/requirements.txt ---> 40490bed96d2 Step 4/4 : RUN pip install --upgrade -r /tmp/requirements.txt ---> Running in a79389decbc4 Collecting ipykernel Downloading ipykernel-6.13.1-py3-none-any.whl (133 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 133.2/133.2 KB 1.4 MB/s eta 0:00:00 Collecting ipython Downloading ipython-8.4.0-py3-none-any.whl (750 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 750.8/750.8 KB 7.4 MB/s eta 0:00:00 Collecting numpy Downloading numpy-1.22.4-cp38-cp38-manylinux_2_17_x86_64.manylinux2014_x86_64.whl (16.9 MB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 16.9/16.9 MB 50.1 MB/s eta 0:00:00 Collecting psutil Downloading psutil-5.9.1-cp38-cp38-manylinux_2_12_x86_64.manylinux2010_x86_64.manylinux_2_17_x86_64.manylinux2014_x86_64.whl (284 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 284.7/284.7 KB 24.1 MB/s eta 0:00:00 Collecting tornado>=6.1 Downloading tornado-6.1-cp38-cp38-manylinux2010_x86_64.whl (427 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 427.5/427.5 KB 38.0 MB/s eta 0:00:00 Collecting packaging Downloading packaging-21.3-py3-none-any.whl (40 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 40.8/40.8 KB 5.0 MB/s eta 0:00:00 Collecting matplotlib-inline>=0.1 Downloading matplotlib_inline-0.1.3-py3-none-any.whl (8.2 kB) Collecting nest-asyncio Downloading nest_asyncio-1.5.5-py3-none-any.whl (5.2 kB) Collecting debugpy>=1.0 Downloading debugpy-1.6.0-cp38-cp38-manylinux_2_5_x86_64.manylinux1_x86_64.manylinux_2_12_x86_64.manylinux2010_x86_64.whl (1.8 MB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 1.8/1.8 MB 71.2 MB/s eta 0:00:00 Collecting traitlets>=5.1.0 Downloading traitlets-5.2.2.post1-py3-none-any.whl (106 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 106.8/106.8 KB 18.8 MB/s eta 0:00:00 Collecting jupyter-client>=6.1.12 Downloading jupyter_client-7.3.3-py3-none-any.whl (131 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 132.0/132.0 KB 18.9 MB/s eta 0:00:00 Collecting pygments>=2.4.0 Downloading Pygments-2.12.0-py3-none-any.whl (1.1 MB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 1.1/1.1 MB 68.7 MB/s eta 0:00:00 Collecting backcall Downloading backcall-0.2.0-py2.py3-none-any.whl (11 kB) Collecting pickleshare Downloading pickleshare-0.7.5-py2.py3-none-any.whl (6.9 kB) Collecting prompt-toolkit!=3.0.0,!=3.0.1,=2.0.0 Downloading prompt_toolkit-3.0.29-py3-none-any.whl (381 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 381.5/381.5 KB 41.8 MB/s eta 0:00:00 Collecting pexpect>4.3 Downloading pexpect-4.8.0-py2.py3-none-any.whl (59 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 59.0/59.0 KB 12.4 MB/s eta 0:00:00 Collecting decorator Downloading decorator-5.1.1-py3-none-any.whl (9.1 kB) Collecting jedi>=0.16 Downloading jedi-0.18.1-py2.py3-none-any.whl (1.6 MB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 1.6/1.6 MB 82.1 MB/s eta 0:00:00 Requirement already satisfied: setuptools>=18.5 in /usr/local/lib/python3.8/site-packages (from ipython->-r /tmp/requirements.txt (line 2)) (57.5.0) Collecting stack-data Downloading stack_data-0.2.0-py3-none-any.whl (21 kB) Collecting parso=0.8.0 Downloading parso-0.8.3-py2.py3-none-any.whl (100 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 100.8/100.8 KB 23.1 MB/s eta 0:00:00 Collecting python-dateutil>=2.8.2 Downloading python_dateutil-2.8.2-py2.py3-none-any.whl (247 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 247.7/247.7 KB 36.0 MB/s eta 0:00:00 Collecting jupyter-core>=4.9.2 Downloading jupyter_core-4.10.0-py3-none-any.whl (87 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 87.3/87.3 KB 21.7 MB/s eta 0:00:00 Collecting entrypoints Downloading entrypoints-0.4-py3-none-any.whl (5.3 kB) Collecting pyzmq>=23.0 Downloading pyzmq-23.1.0-cp38-cp38-manylinux_2_12_x86_64.manylinux2010_x86_64.whl (1.1 MB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 1.1/1.1 MB 68.4 MB/s eta 0:00:00 Collecting ptyprocess>=0.5 Downloading ptyprocess-0.7.0-py2.py3-none-any.whl (13 kB) Collecting wcwidth Downloading wcwidth-0.2.5-py2.py3-none-any.whl (30 kB) Collecting pyparsing!=3.0.5,>=2.0.2 Downloading pyparsing-3.0.9-py3-none-any.whl (98 kB) ━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━━ 98.3/98.3 KB 19.7 MB/s eta 0:00:00 Collecting executing Downloading executing-0.8.3-py2.py3-none-any.whl (16 kB) Collecting asttokens Downloading asttokens-2.0.5-py2.py3-none-any.whl (20 kB) Collecting pure-eval Downloading pure_eval-0.2.2-py3-none-any.whl (11 kB) Collecting six>=1.5 Downloading six-1.16.0-py2.py3-none-any.whl (11 kB) Installing collected packages: wcwidth, pure-eval, ptyprocess, pickleshare, executing, backcall, traitlets, tornado, six, pyzmq, pyparsing, pygments, psutil, prompt-toolkit, pexpect, parso, numpy, nest-asyncio, entrypoints, decorator, debugpy, python-dateutil, packaging, matplotlib-inline, jupyter-core, jedi, asttokens, stack-data, jupyter-client, ipython, ipykernel Successfully installed asttokens-2.0.5 backcall-0.2.0 debugpy-1.6.0 decorator-5.1.1 entrypoints-0.4 executing-0.8.3 ipykernel-6.13.1 ipython-8.4.0 jedi-0.18.1 jupyter-client-7.3.3 jupyter-core-4.10.0 matplotlib-inline-0.1.3 nest-asyncio-1.5.5 numpy-1.22.4 packaging-21.3 parso-0.8.3 pexpect-4.8.0 pickleshare-0.7.5 prompt-toolkit-3.0.29 psutil-5.9.1 ptyprocess-0.7.0 pure-eval-0.2.2 pygments-2.12.0 pyparsing-3.0.9 python-dateutil-2.8.2 pyzmq-23.1.0 six-1.16.0 stack-data-0.2.0 tornado-6.1 traitlets-5.2.2.post1 wcwidth-0.2.5 WARNING: Running pip as the 'root' user can result in broken permissions and conflicting behaviour with the system package manager. It is recommended to use a virtual environment instead: https://pip.pypa.io/warnings/venv WARNING: You are using pip version 22.0.4; however, version 22.1.2 is available. You should consider upgrading via the '/usr/local/bin/python -m pip install --upgrade pip' command. Removing intermediate container a79389decbc4 ---> 942cfb92669c Successfully built 942cfb92669c Successfully tagged ************:5005/docker/registry/anikishin_proj3:latest $ docker push ************:5005/docker/registry/$_$:$ The push refers to repository [************:5005/docker/registry/anikishin_proj3] ca238036b879: Preparing 5083b2b128f1: Preparing 92487648c84b: Preparing 9df5b2f53554: Preparing 590db2877d9d: Preparing 3d5419adeeb6: Preparing 2c9f341968bc: Preparing ad6562704f37: Preparing 2c9f341968bc: Waiting 3d5419adeeb6: Waiting ad6562704f37: Waiting 92487648c84b: Pushed 5083b2b128f1: Pushed 590db2877d9d: Pushed 2c9f341968bc: Pushed 9df5b2f53554: Pushed 3d5419adeeb6: Pushed ca238036b879: Pushed latest: digest: sha256:bc36a9bcc6be914a9b7f8ee6ea6c940409f32c57a528c521651442235309239a size: 1996 Running after_script 00:00 Saving cache 00:00 Uploading artifacts for successful job 00:00 Uploading artifacts. Runtime platform arch=amd64 os=linux pid=27359 revision=c5874a4b version=12.10.2 ./.env: found 1 matching files Uploading artifacts to coordinator. ok responseStatus=201 Created token=************ Job succeeded Какие проблемы могут возникнуть
У нас все получилось не сразу. По пути возникали проблемы, из-за которых мы не смогли быстро перейти на новую схему:
1. Нет онбординга
Понадобилось некоторое время на обучение дата саентистов работе с докер-образами;
Изначально у коллег не было понимания, что данные в контейнере не сохранятся если их не писать в специальную директорию. Плюс ваши дата саентисты должны знать, что простого pip install может оказаться недостаточно: в контейнере должны быть установлены дополнительные зависимости, если этого требует Python-модуль.
Решение: сделайте инструкцию, проводите онбординг новых сотрудников, помогайте в случае проблем со сборкой кернелов.
2. Сохранность данных
Поскольку kernel’ы работают в докер-образах, то их перезагрузка приводит к потере всех сохраненных данных.
Решение: создайте отдельную общую папку на сервере, которая монтируется к докер-образу и в которую сохраняются все необходимые дата саентисту артефакты.
3. Ограничение ресурсов
Без лимитов и рычагов один дата саентист может навалить такую нагрузку, что другие не смогут нормально работать:

Это один контейнер с kernel.
И так может случиться не один раз
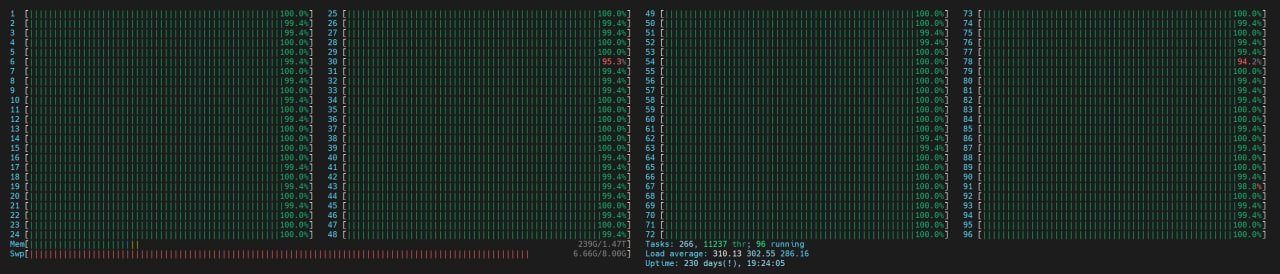
Решение: мониторьте нагрузку по CPU\RAM. Когда получаете алерт определяйте кто грузит машину и идите наказывать виновника попросите коллегу сбавить обороты.
4. Версионность
Как мы пришли к тегу #latest: изначально мы планировали версионировать все создаваемые докер-образы. Но дата саентисты стали делать такое множество версий своих образов, что в результате место в Docker registry быстро закончилось.
Решение: используйте версионность только для продуктивных процессов.
Планы на развитие
Резюмируя: мы получили современное решение, дата саентисты больше не дергают админов, они рады что могут самостоятельно править свои kernel в любое время, не прибегая к помощи со стороны.
Сейчас мы думаем о том, как реализовать удобное и гибкое ограничение ресурсов для контейнеров. Если у вас есть идеи как это сделать — напишите в комментариях.
- Блог компании Ростелеком
- Системное администрирование
- Python
- Data Mining